UUID v4 vs UUID v7: Why Database Keys Are Ditching v4
Random UUID v4 crushes B-tree database indexes with constant page splits. UUID v7 prefixes a 48-bit timestamp to keep inserts fast and sequential.
If you are choosing a primary key for a new database table today, the quick answer is simple: use UUID v7 for database records, and save UUID v4 for public security tokens.
UUID v4 is entirely random. That randomness protects security tokens from being guessed, but it wrecks relational database indexes. UUID v7 solves that problem by putting a 48-bit Unix timestamp at the front. You get the distributed uniqueness of a UUID with the write speed of an auto-incrementing integer.
You can inspect and test both formats in your browser with our UUID generator.
Here is why databases struggle with v4, how v7 fixes it, and when to pick each one.
The B-tree write penalty in UUID v4
Relational databases like PostgreSQL, MySQL (InnoDB), and SQLite organize primary key indexes using B-trees. A B-tree keeps its data sorted on disk in fixed-size blocks called pages (typically 8 KB in Postgres or 16 KB in MySQL).
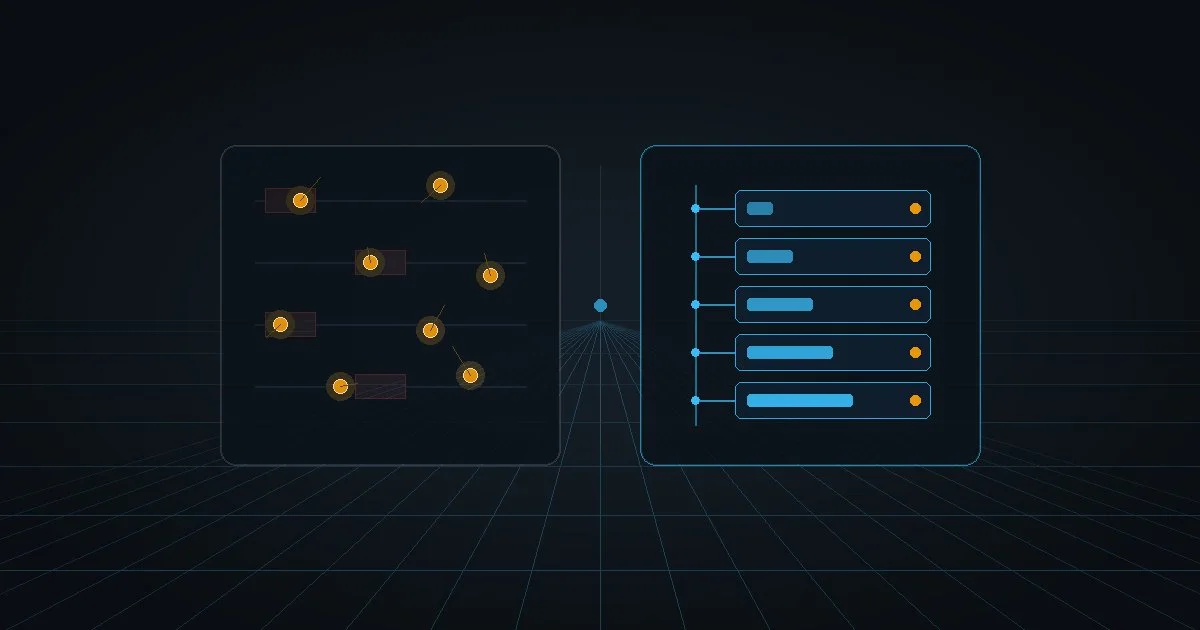
When you use an auto-incrementing integer (1, 2, 3...), new records always land on the rightmost leaf page of the tree. The database fills that page, marks it done, and opens a new one. The active page stays hot in RAM, and disk writes stay sequential.
UUID v4 breaks that completely. Because all 122 data bits are random, an ID generated right now could start with 0x01 and the next one could start with 0xfe.
UUID v4:   f47ac10b-58cc-4372-a567-0e02b2c3d479  (Completely random)
UUID v4:   1a2b3c4d-5e6f-4a8b-9c0d-1e2f3a4b5c6d  (Scattered anywhere in index)
Every single insert lands on an arbitrary page in your index. As soon as your table outgrows your server’s RAM buffer pool, three things happen:
- Cache thrashing: The database must constantly fetch cold index pages from disk to write a single row.
- Page splits: When a random insert targets an 8 KB page that is already full, the engine must split it in half, allocate a new page, and rewrite parent pointers.
- Index bloat: Because pages split unevenly, B-tree indexes end up half-empty on disk, consuming twice as much storage and write-ahead log (WAL) bandwidth.
On tables with tens of millions of rows, write throughput on UUID v4 tables can drop by 50% to 80% compared to sequential IDs.
How UUID v7 fixes the index
UUID v7, standardized in RFC 9562, is designed specifically for database performance.
Instead of filling all 128 bits with random noise, UUID v7 dedicates the first 48 bits to a millisecond-precision Unix timestamp. The remaining bits contain sub-millisecond counters and cryptographic randomness.
       48-bit Unix Timestamp          Ver  Rand   Var   Random Bits
|------------------------------------|---|------|----|----------------|
  018e24a8-6b20-                      7   1a2    b   3c4d5e6f7a8b
Because the timestamp sits at the front of the string, IDs generated over time naturally sort in chronological order.
When you insert a batch of UUID v7 records, they cluster on the current rightmost leaf page of your B-tree. Your active page stays cached in memory, page splits plummet, and your index footprint remains compact.
If you work with timestamps across systems, check our Unix timestamp guide to understand how millisecond ranges operate under the hood.
When should you still use UUID v4?
UUID v7 is better for database indexing, but it is not a drop-in replacement for every use case.
Because UUID v7 contains a timestamp, anyone who inspects the ID can extract the exact millisecond it was created. They can also estimate how many records your application creates between two known points in time.
Use UUID v4 when: - You need opaque public tokens, like password reset links or invite codes. - You do not want competitors guessing your order volume or signup rate. - The identifier is stored in a hash map or cache key rather than a sorted B-tree.
Use UUID v7 when:
- You need a primary key or clustered index in PostgreSQL, MySQL, SQLite, or CockroachDB.
- Multiple distributed services create records without a central database sequence.
- You want to sort records chronologically directly by their primary key without adding a separate created_at index.
Quick reference comparison
| Feature | UUID v4 | UUID v7 |
|---|---|---|
| Standard | RFC 4122 | RFC 9562 |
| Leading bits | Random | 48-bit Unix epoch timestamp |
| B-tree insert pattern | Random scatter (causes page splits) | Sequential append (cache-friendly) |
| Index fragmentation | High | Low |
| Exposes creation time | No (purely opaque) | Yes (millisecond precision) |
| Best suited for | Security tokens and invite links | Database primary keys and event logs |
Whenever you need to generate either format for local testing, schema migrations, or development mocks, open the ToolQuilt UUID generator to create cryptographically secure v4 and v7 identifiers instantly.